diff --git a/README.md b/README.md
index 61e4ec8..d3483ae 100644
--- a/README.md
+++ b/README.md
@@ -108,7 +108,7 @@ To see a survey of RGBD datasets, check out Michael Firman's [collection](http:/
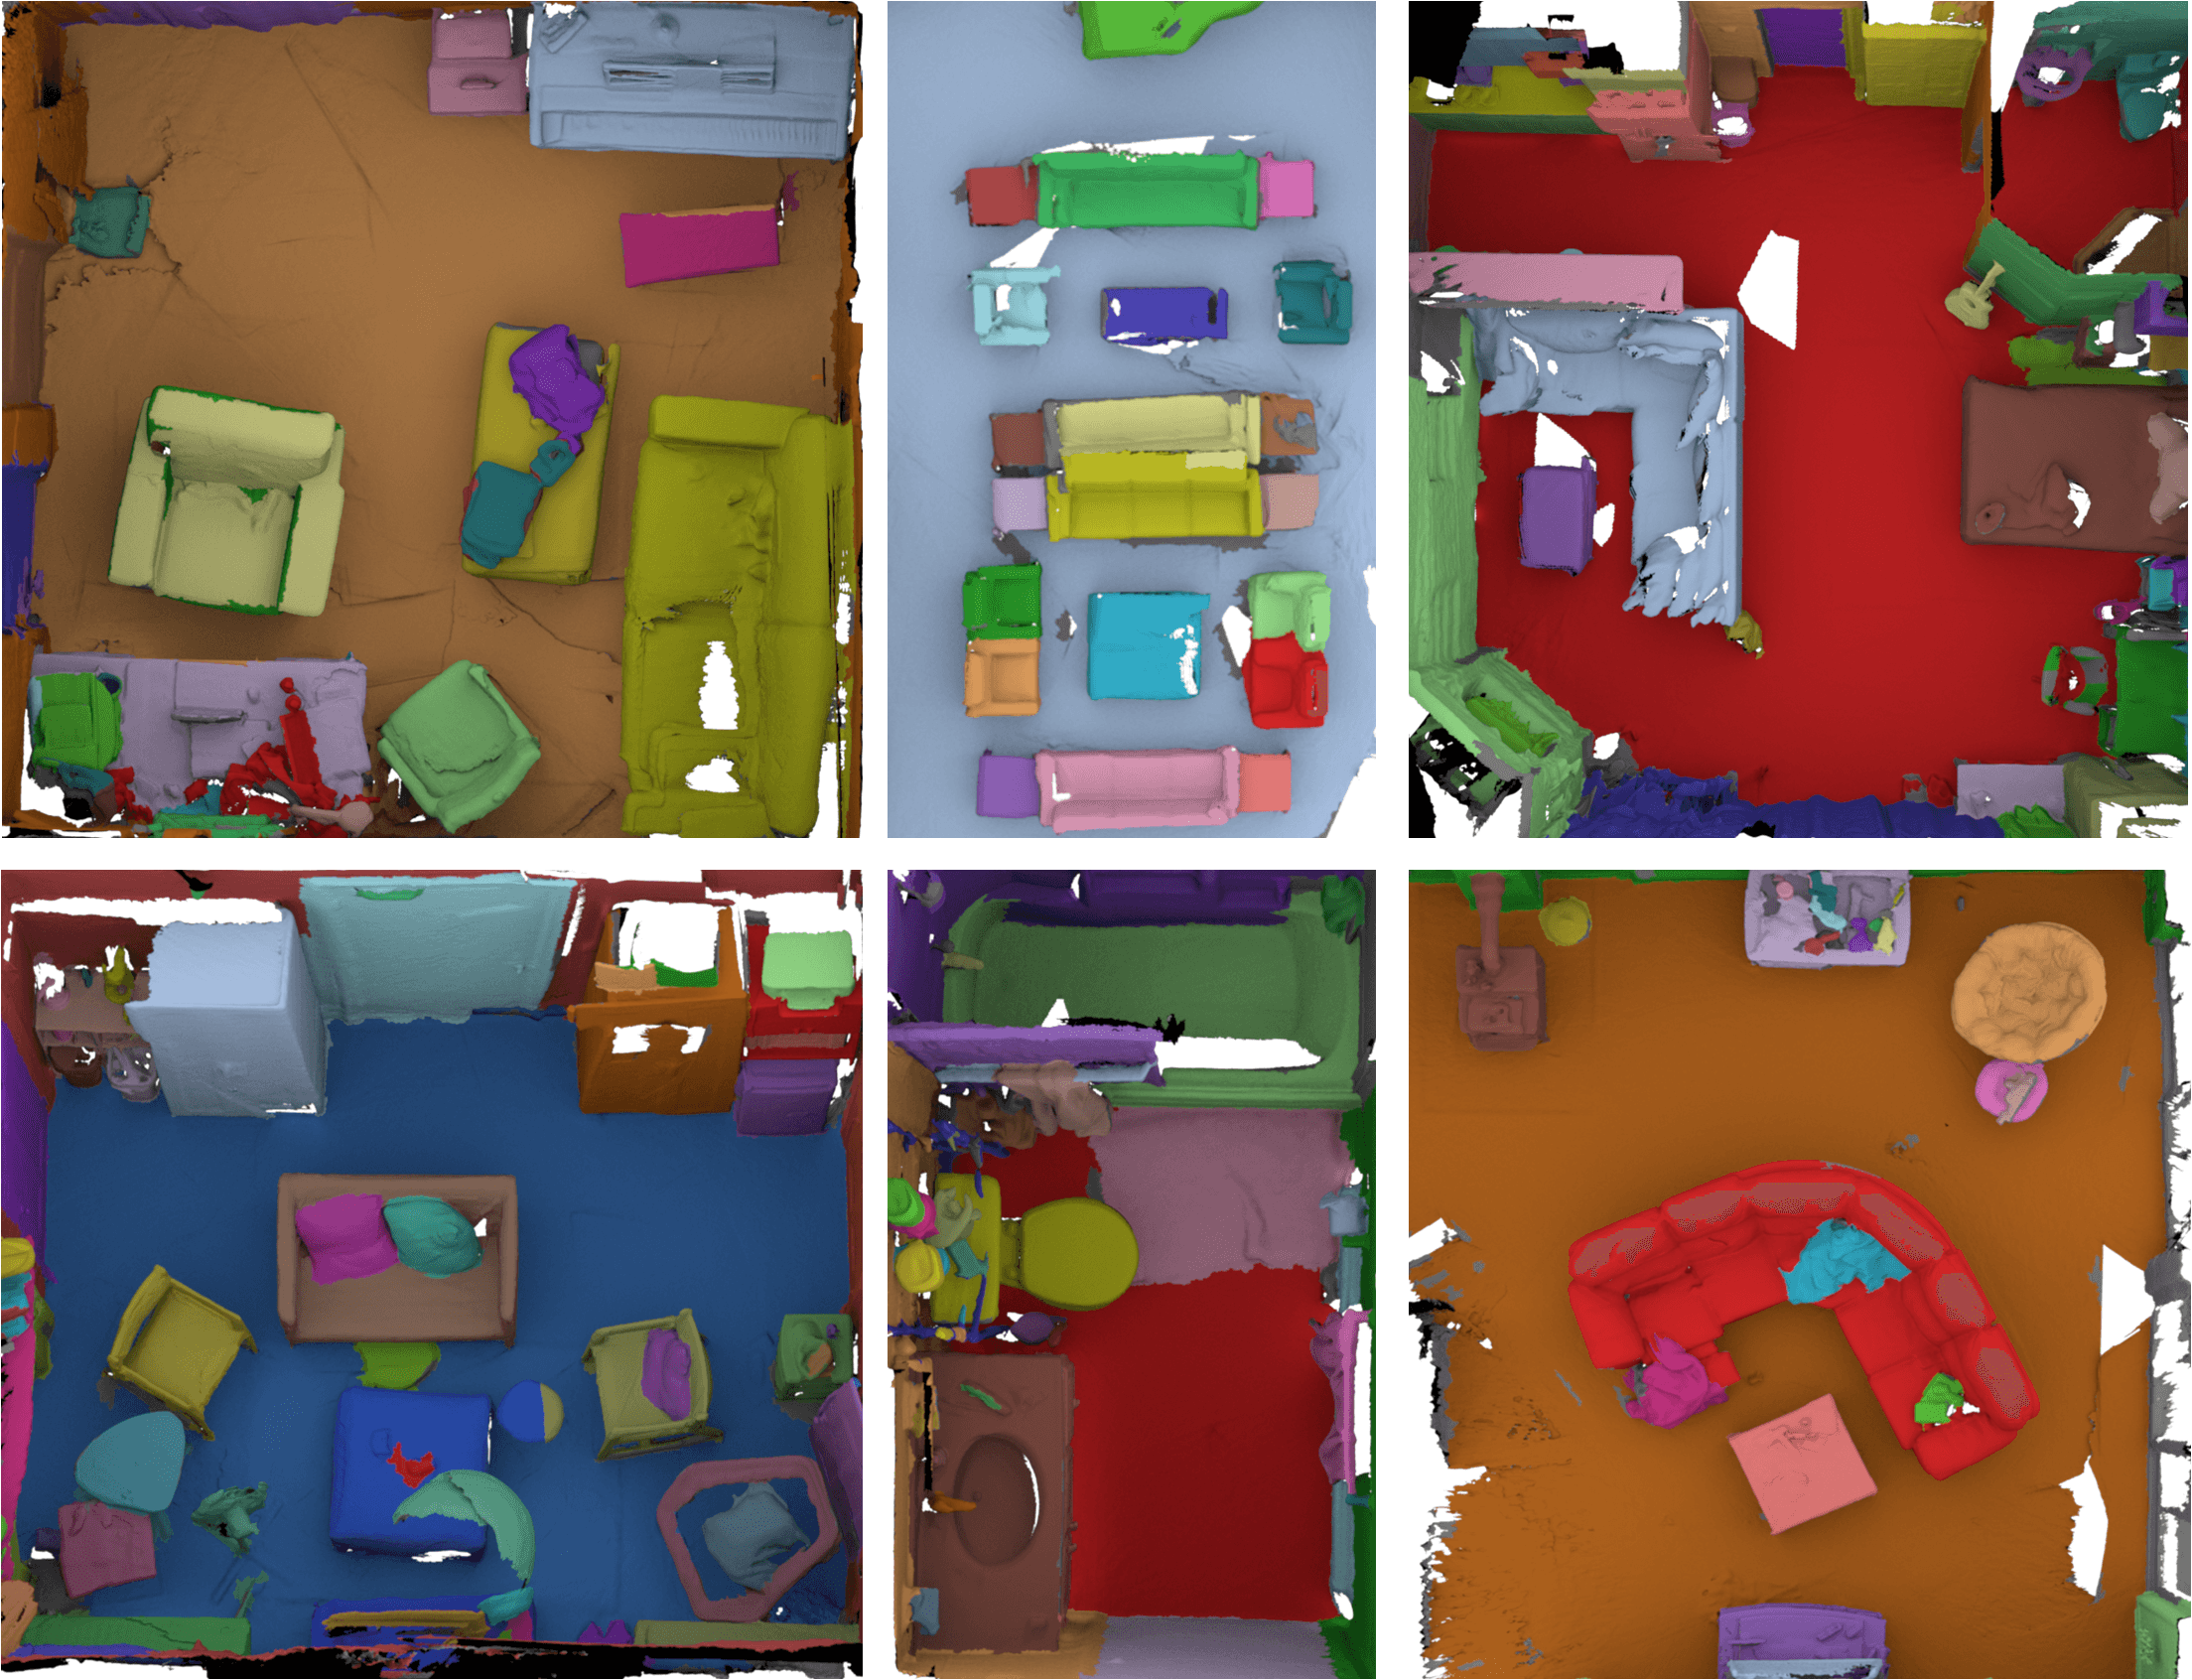
ScanNet (2017) [[Link]](http://www.scan-net.org/)
An RGB-D video dataset containing 2.5 million views in more than 1500 scans, annotated with 3D camera poses, surface reconstructions, and instance-level semantic segmentations.
-
+
Matterport3D: Learning from RGB-D Data in Indoor Environments (2017) [[Link]](https://niessner.github.io/Matterport/)
10,800 panoramic views (in both RGB and depth) from 194,400 RGB-D images of 90 building-scale scenes of private rooms. Instance-level semantic segmentations are provided for region (living room, kitchen) and object (sofa, TV) categories.
@@ -288,6 +288,9 @@ To see a survey of RGBD datasets, check out Michael Firman's [collection](http:/
Learning Hierarchical Shape Segmentation and Labeling from Online Repositories (2017) [[Paper]](http://cs.stanford.edu/~ericyi/project_page/hier_seg/index.html)

+:space_invader: ScanNet (2017) [[Paper]](https://arxiv.org/pdf/1702.04405.pdf) [[Code]](https://github.com/scannet/scannet)
+
+
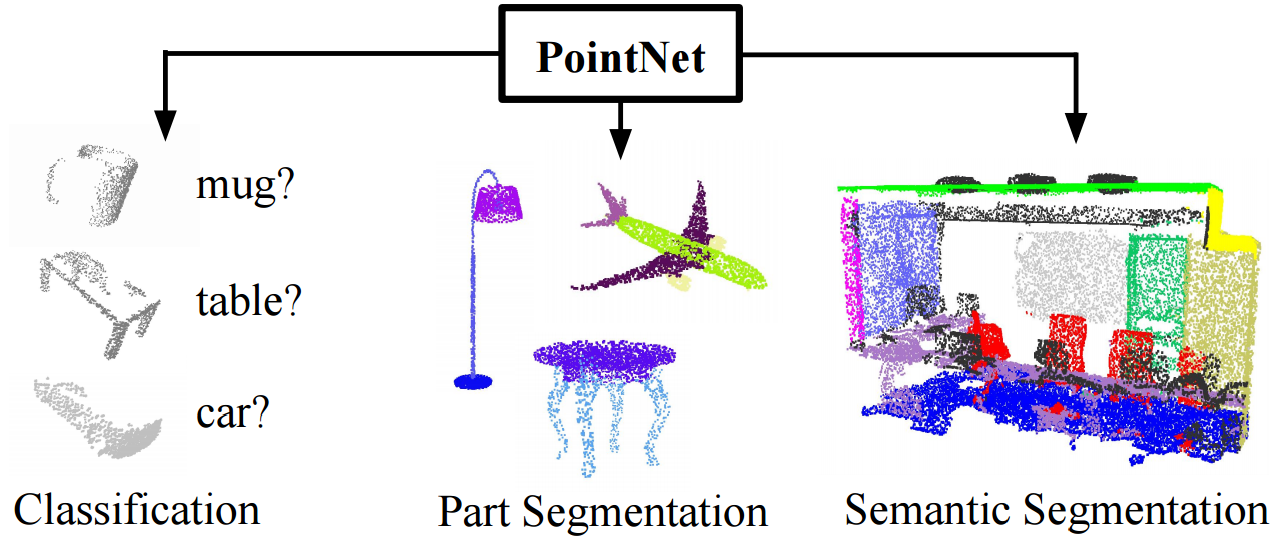
:game_die: PointNet: Deep Learning on Point Sets for 3D Classification and Segmentation (2017) [[Paper]](http://stanford.edu/~rqi/pointnet/) [[Code]](https://github.com/charlesq34/pointnet)
@@ -316,6 +319,9 @@ Parsing of Large-scale 3D Point Clouds (2017) [[Paper]](https://arxiv.org/pd
:game_die: PointCNN (2018) [[Paper]](https://yangyanli.github.io/PointCNN/)

+:camera::space_invader: 3DMV: Joint 3D-Multi-View Prediction for 3D Semantic Scene Segmentation (2018) [[Paper]](https://arxiv.org/pdf/1803.10409.pdf)
+
+
## 3D Model Synthesis/Reconstruction
@@ -438,6 +444,9 @@ _Deep Learning Methods_
:camera: Synthesizing 3D Shapes via Modeling Multi-View Depth Maps and Silhouettes with Deep Generative Networks (2017) [[Paper]](http://openaccess.thecvf.com/content_cvpr_2017/papers/Soltani_Synthesizing_3D_Shapes_CVPR_2017_paper.pdf) [[Code]](https://github.com/Amir-Arsalan/Synthesize3DviaDepthOrSil)

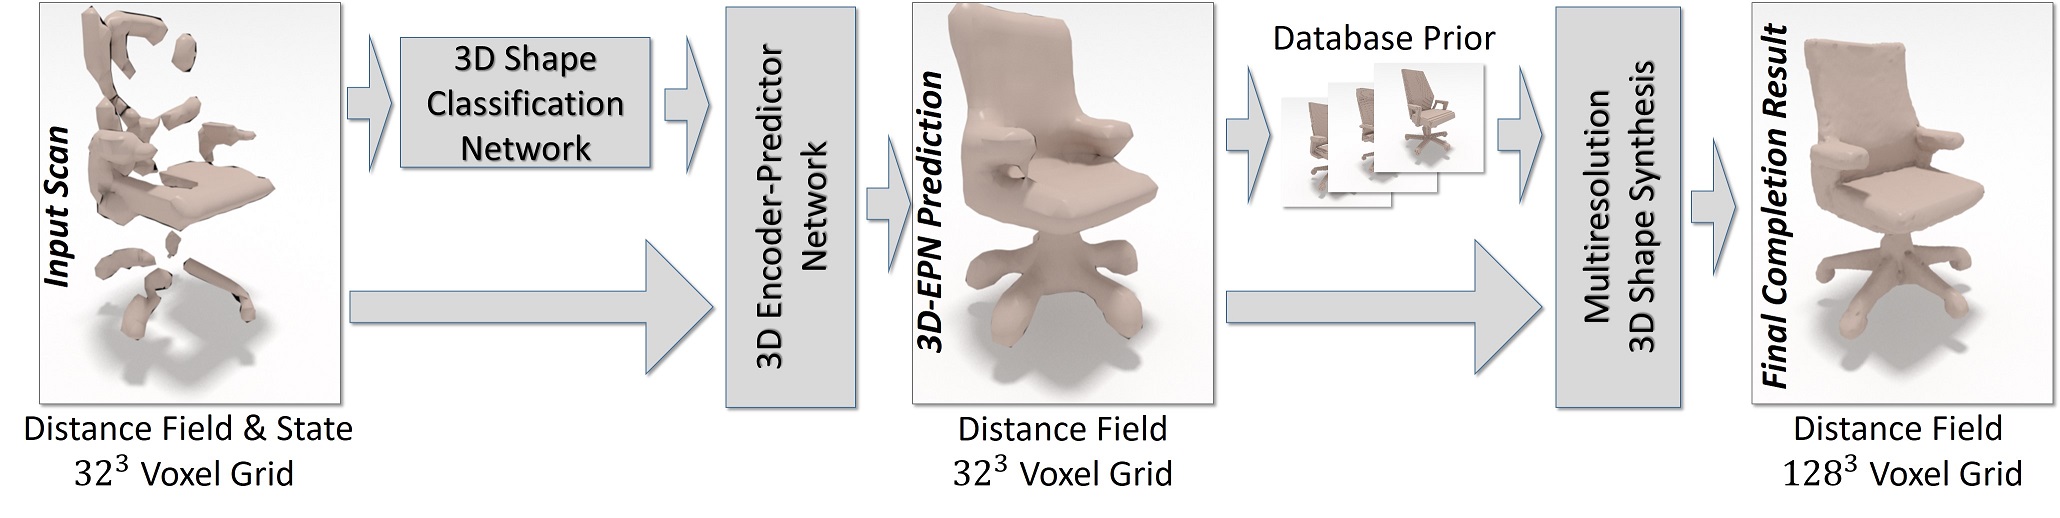
+:space_invader: Shape Completion using 3D-Encoder-Predictor CNNs and Shape Synthesis (2017) [[Paper]](https://arxiv.org/pdf/1612.00101.pdf) [[Code]](https://github.com/angeladai/cnncomplete)
+
+
:space_invader: Octree Generating Networks: Efficient Convolutional Architectures for High-resolution 3D Outputs (2017) [[Paper]](https://arxiv.org/pdf/1703.09438.pdf) [[Code]](https://github.com/lmb-freiburg/ogn)

@@ -647,3 +656,6 @@ _Deep Learning Methods_
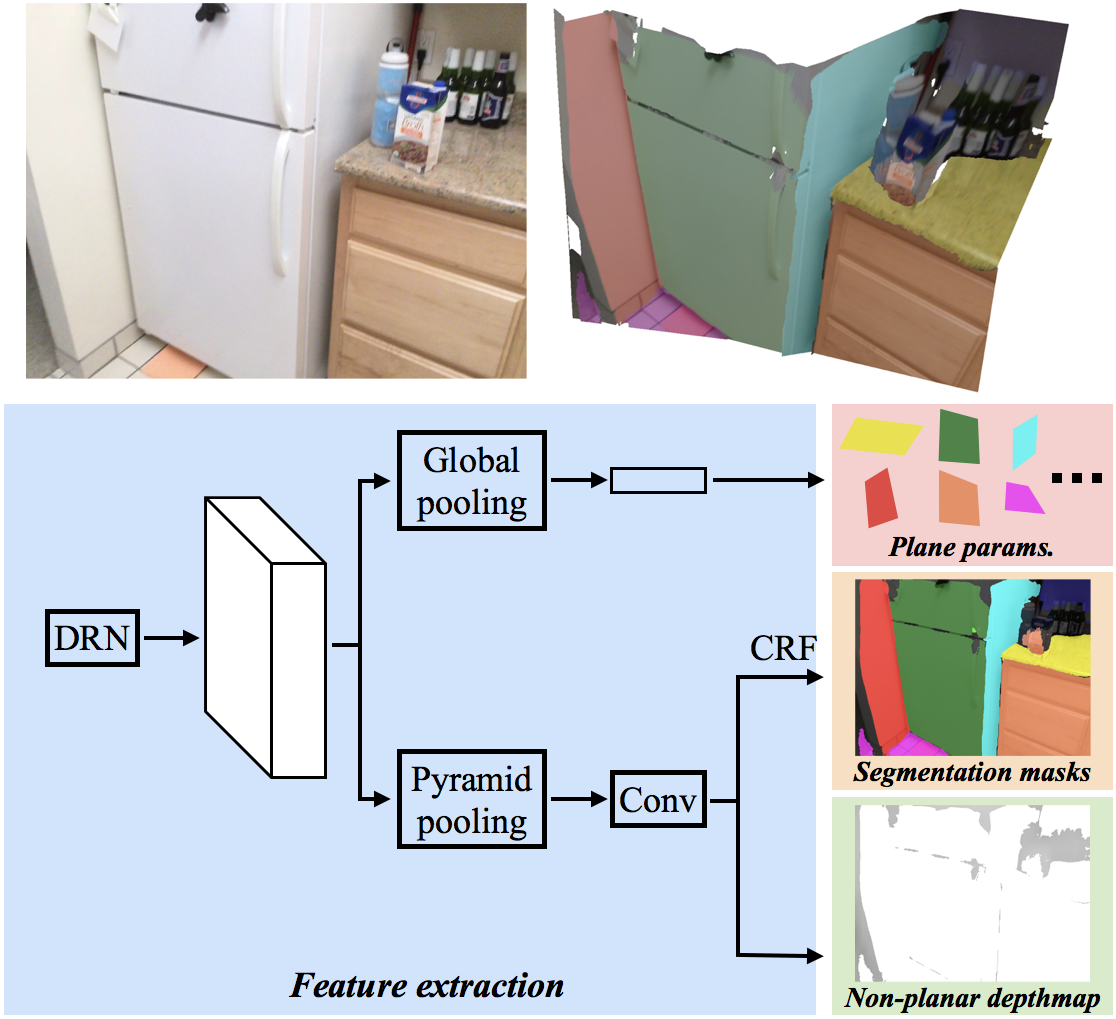
PlaneNet: Piece-wise Planar Reconstruction from a Single RGB Image (2018 CVPR) [[Paper]](http://art-programmer.github.io/planenet/paper.pdf) [[Code]](http://art-programmer.github.io/planenet.html)
+
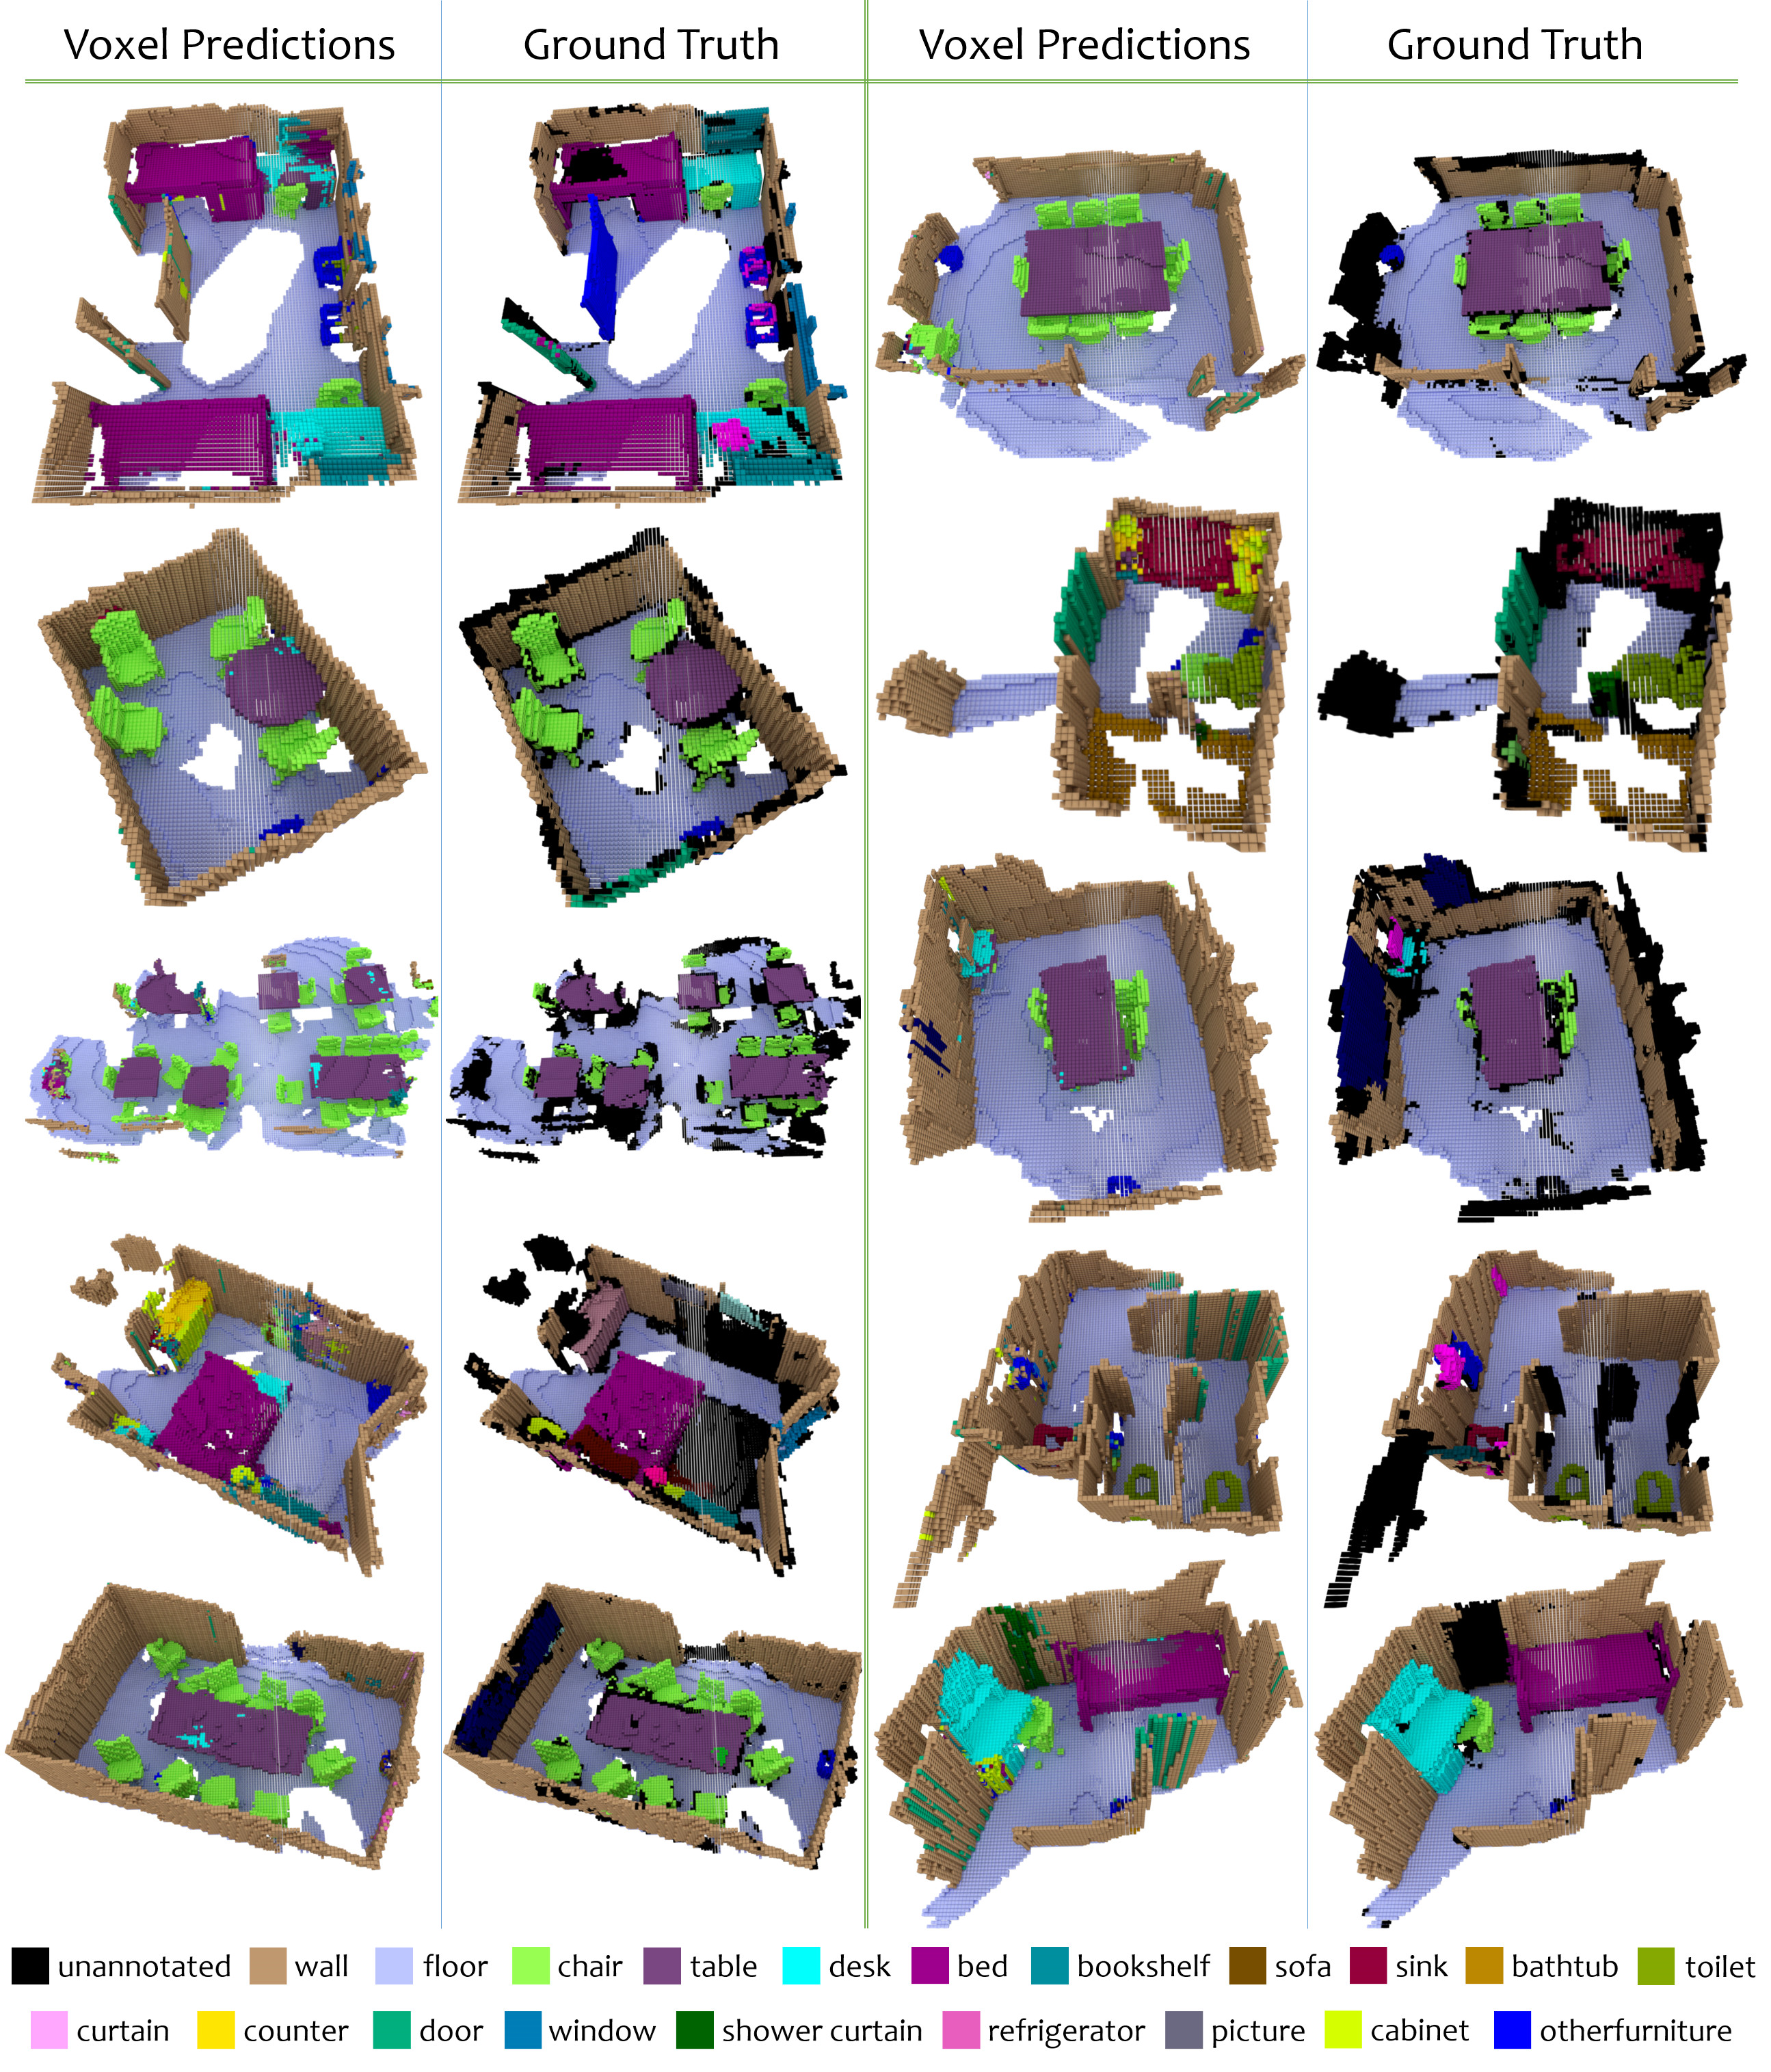
+:space_invader: ScanComplete: Large-Scale Scene Completion and Semantic Segmentation for 3D Scans (2018) [[Paper]](https://arxiv.org/pdf/1712.10215.pdf)
+
\ No newline at end of file